
Mainstream is the largest provider of innovative cloud solutions and managed hosting services with a network of 10+ data centers in Southeast Europe.


We design recovery around the targets you set, and the documentation a review asks for comes out of the tests we run. Both halves of the job go through one contract and one team.
Contact us
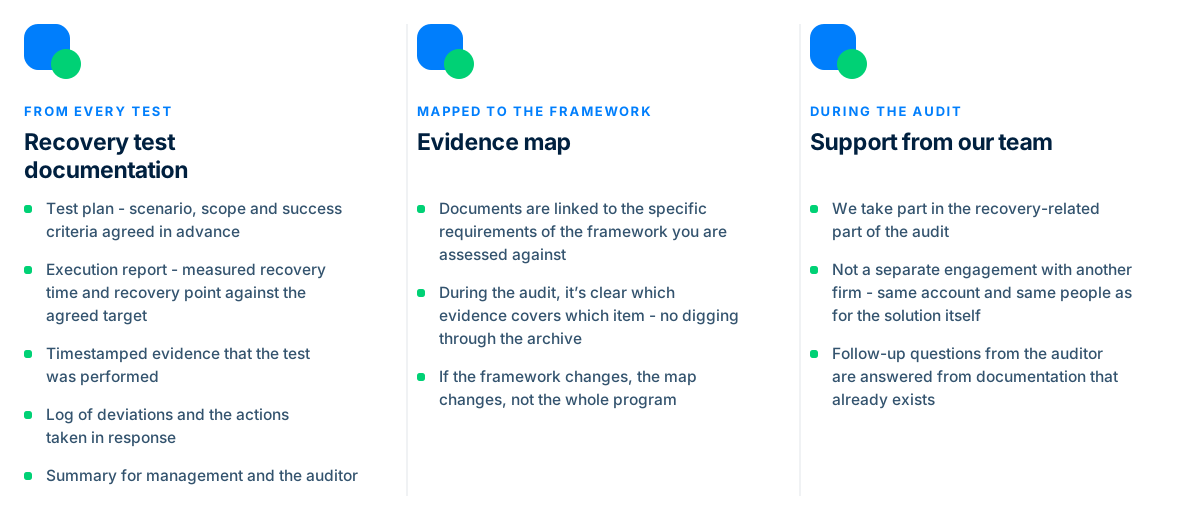
When you operate under regulation, the question at a review is not whether you have a recovery plan, but what you use to prove it works. They ask for the test plan, the measured result against the target, and a record of what was done when a test did not go as it should.
That work usually lands on the IT team, on top of everything else they already do, or it is handed to a consultancy that took no part in the recovery itself. Either way, the documentation sooner or later stops matching the real state of the systems.
With us the two jobs are not separated: the same team sets up and runs the recovery solution and prepares the documentation that comes out of the tests carried out.


Operators of ICT systems of special importance — obligations around continuity and recovery, subject to review by the competent authority.

Requirements for managing ICT risk and continuity, with testing and documentation of the results.

If you are certifying or maintaining a certificate, recovery of the IT systems is one of the proofs required at the review.

The obligation increasingly arrives through a contract rather than a regulation — and the same proof is required then too.
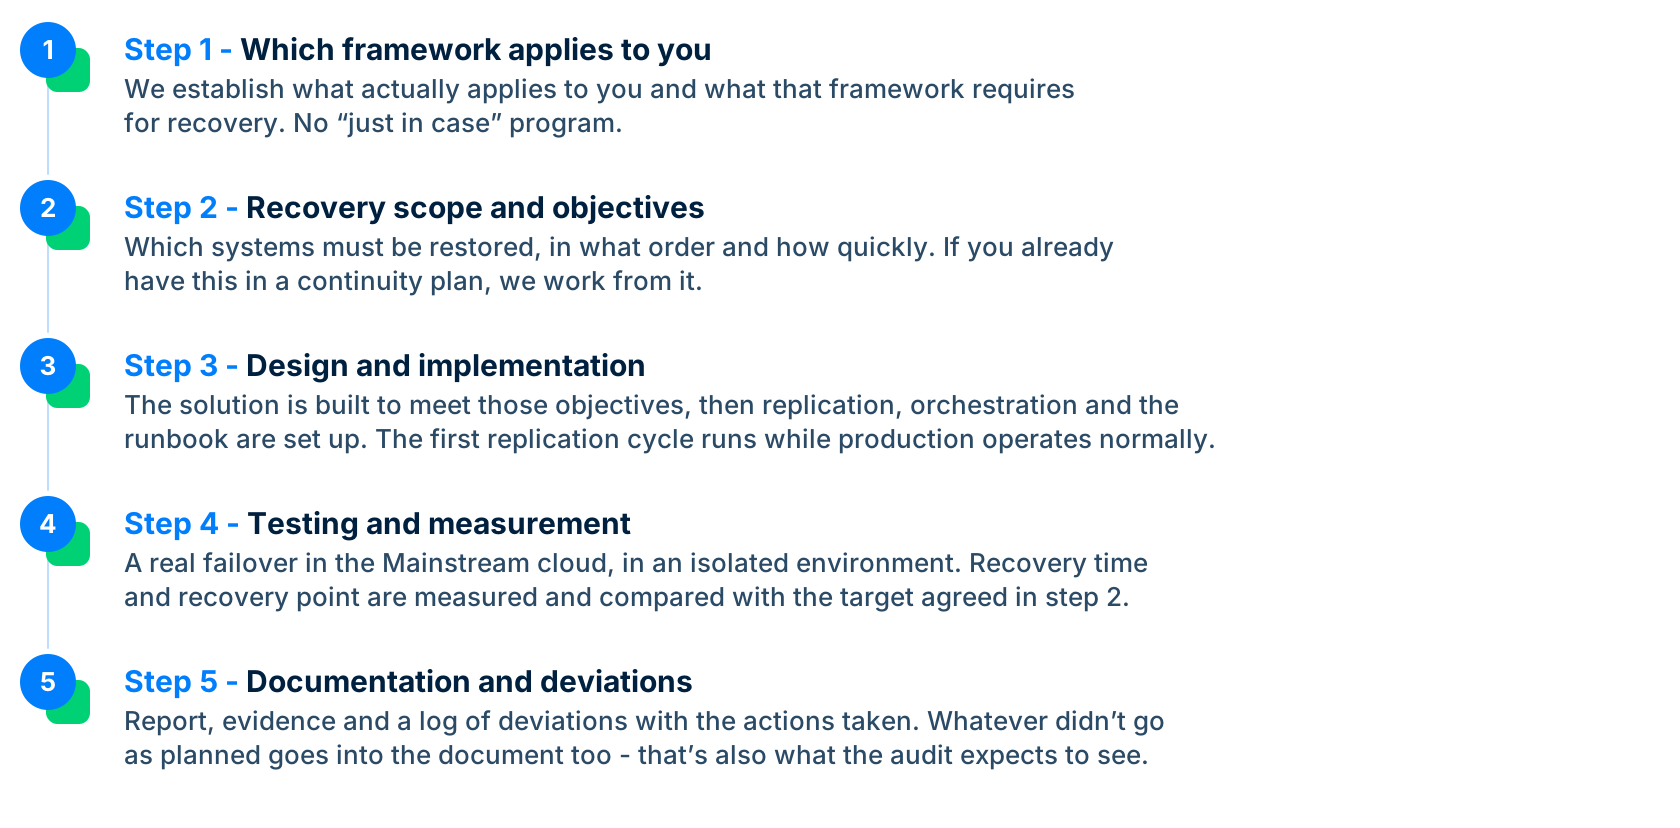
Recovery targets aren’t discovered at the end — they’re set at the start.
We start from what the business requires and what the framework you’re assessed against requires: which processes must not stop, how long they can be unavailable and how much data may be lost. If you already have this defined in a continuity plan, we work to it. If you don’t, we set the targets together with you. The solution is then designed to meet those targets, and a test at the end of implementation confirms that it does and that same test is later what proves recovery works.
Replication runs from the environment you work in today into Mainstream Cloud. What differs from client to client:
Production stays where it is — on your premises, in your data center or with the provider you use today.
RTO and RPO are set according to what the business requires, and the solution is designed to meet them.
The requirements of the framework that applies to you go into the design, rather than being added afterwards.
Locations in the region and in the European Union, according to where the data is allowed to reside.
The foundation is Cloud DR. Mainstream DR runs on HPE Zerto technology, with a procedure prepared in advance for switching over to the recovery site and back.

Changes are carried over continuously, not in scheduled cycles. Production runs normally while replication is under way.

The virtual machines of a single application are recovered to the same point in time, in a predefined startup order.

The journal keeps recovery points going back, up to 30 days by agreement. Longer retention on immutable storage, which not even an administrator can alter.

The test environment is isolated. One test per year per protected system is included in the service — 12 hours of test run time, scheduled in advance.
The solution is run managed or self-managed. For entities under regulation the managed option usually makes more sense, because oversight, running the tests and the reports then sit with us.
The foundation is Cloud DR. Mainstream DR runs on HPE Zerto technology, with a procedure prepared in advance for switching over to the recovery site and back.
Tell us which framework and which deadline — we'll walk through what needs to be in place on the recovery side by then.
Our network of more than 10 data centers and strong regional presence give you the flexibility to choose the location for your disaster recovery needs, backed by reliable connectivity and enterprise-grade infrastructure to protect your critical workloads.
By combining robust infrastructure, cloud expertise, and an in-depth understanding of local business needs, we deliver disaster recovery solutions tailored to each client.

Frameworks require testing at intervals, not once. That is why the programme runs in a cycle, and each cycle refreshes the documentation — two-year-old evidence isn't worth much at a review.
On top of that, we track what changes in the regulations and adapt the programme. Keeping up with the changes doesn't have to be your job.
The programme relies on the test that is already part of the Cloud DR service. If the framework you're assessed against requires more frequent testing or a specific scenario, that is arranged as part of the programme.
Mainstream combines regional cloud infrastructure with years of experience in delivering disaster recovery solutions.
Our teams have implemented DR projects for organizations across the financial services, retail, manufacturing, SaaS, and other industries, developing an in-depth understanding of diverse business, operational, and regulatory requirements. We tailor each solution to the client's environment and recovery priorities, ensuring that our services not only meet local requirements but go beyond the standard approach.
Key Benefits:


We go through:


Mainstream is the largest provider of innovative cloud solutions and managed hosting services with a network of 10+ data centers in Southeast Europe.
Mainstream 2012-2026 All rights reserved.